
The race to build ever-larger AI data centres has moved the hard problem from buying chips to keeping them busy. Facilities that Nvidia calls AI factories now tie together hundreds of thousands of GPUs over high-speed networks, and every hour a cluster sits stalled is expensive capacity producing nothing.
Nvidia's answer, unveiled on Thursday, 22 October 2026, at its GTC Berlin conference, which ran from 20 to 22 October, is Minerva, an AIOps platform for running that infrastructure. The company pitches it as a way for operations teams to spot problems before they spread. It was one of a long list of announcements at the event, alongside general availability of Vera Rubin-based instances on Google Cloud.
At this scale, a single weak component can hold back an entire training job. A GPU running hotter than its neighbours, or an NVMe drive that slows down under heavy load, is exactly the kind of warning sign that slips past unnoticed. Conventional monitoring, Nvidia argues, leaves the networking, compute, reliability and machine learning teams each looking at their own slice, so nobody gets the whole picture. "Minerva is designed to catch those early warning signs," wrote Brian Sparks, a senior director of marketing for Nvidia's networking platforms.
Minerva pulls telemetry from Nvidia GPUs, Spectrum-X Ethernet, NVLink switches, SuperNICs and DPUs, from job schedulers such as Slurm and Nvidia Run:ai, and from the AI workloads themselves. With that data it builds a live knowledge graph linking GPUs, network cards, switches and cables to the jobs running across them. An operator can then follow a sluggish training run back to the part responsible, even in a site with hundreds of thousands of GPUs.
Under the hood, the platform processes billions of data points every hour, applying both supervised and unsupervised machine-learning models. It learns what normal behaviour looks like, flags anomalies it has never encountered, predicts failures while they are still developing and folds floods of related alerts into single incidents, each with a probable root cause. A built-in assistant answers operators' questions in plain language, grounded in live data, and recommends fixes. It can also hand off to external agentic AI tools, and remedies can be applied by hand or automated through infrastructure APIs.
Nvidia frames the payoff in terms of AI factory yield, meaning the useful work a site turns out, tracked through GPU hours, goodput, cluster uptime and tokens generated. It promises three results: longer stretches between interruptions thanks to predictive maintenance, quicker repairs and less alert noise. The company has not put numbers on those gains, nor has it published pricing.
IREN, which runs AI data centres, is already using Minerva. "NVIDIA Minerva gives our operations team one view across the network, the GPUs and the jobs running on them," said chief technology officer Denis Skrinnikoff, adding that the tool lets the team spend more time on preventive work instead of chasing faults. Seven more names, including IBM, Tesla, Jio, Lambda, Bitdeer AI, Aolani and Quake AI, intend to roll it out.
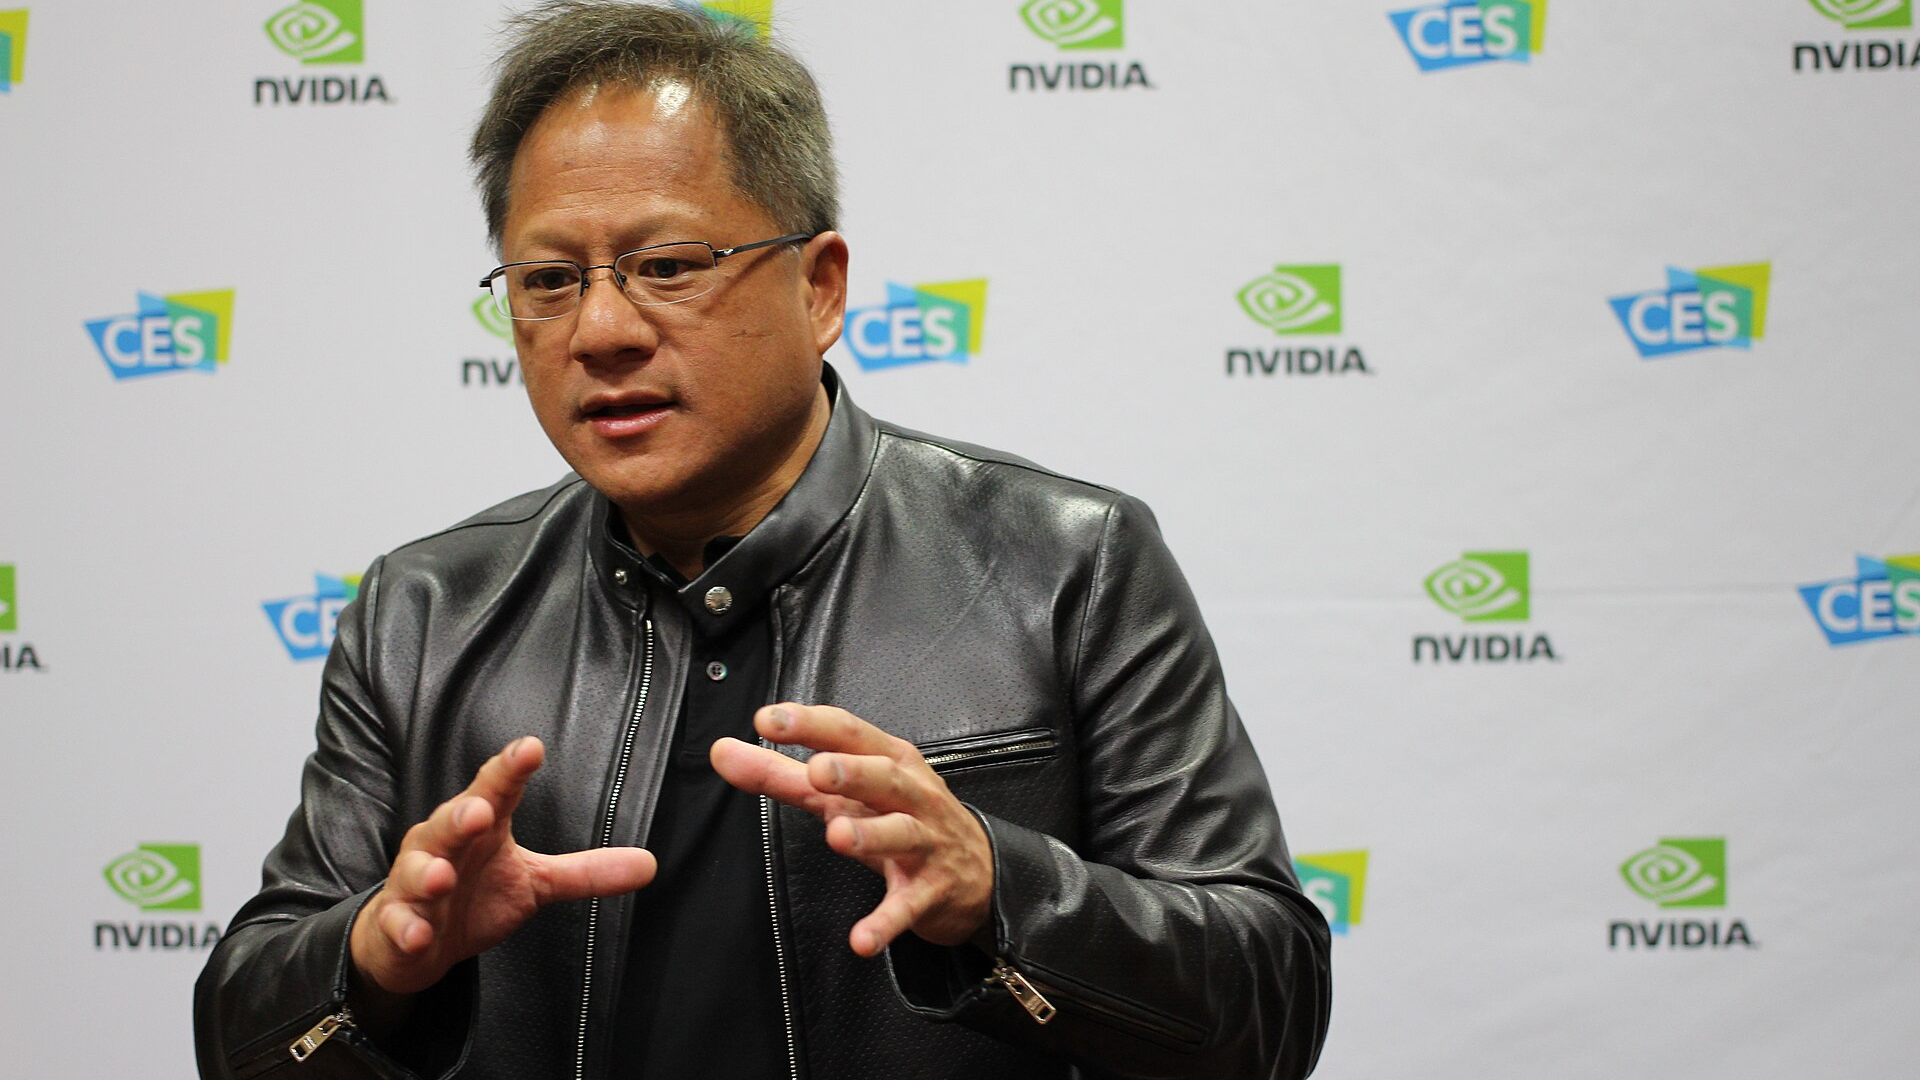
Server makers Dell Technologies, Lenovo and Supermicro will bundle Minerva into the tools they sell for running AI factories, and the software forms part of Nvidia's full-stack Vera Rubin platform. Chief executive Jensen Huang delivered the conference keynote at Berlin's Tempodrom on 21 October.